6 posts tagged with "ANR"

View All Tags

Silent Failures, ANRs, and App Hangs: How to Detect and Fix the Bugs That Never Crash

Published: · 15 min read
Don Peter
Cofounder and CTO, Appxiom

Your crash reporting dashboard displays a pristine 99.9% crash-free session rate.

Your engineering team celebrates a successful deployment. The release metrics look flawless. But on the App Store and Google Play, your reviews tell a completely different story:

"The app freezes every time I tap the checkout button. Completely unusable."
"It just spins forever on the login screen. Had to force close and uninstall."
"Buttons become unresponsive after opening my transaction history."

Meanwhile, your product manager pulls up analytics: checkout funnel completion has plummeted by 22%, and customer churn is spiking. Yet your error monitor reports zero fatal crashes.

How can an application be catastrophic for users while registering as 100% healthy on your APM dashboard?

Welcome to the blind spot of modern software monitoring: Silent Failures, Application Not Responding (ANR) events, and iOS App Hangs.

The Dangerous Illusion of the Crash-Free Rate​

For more than a decade, mobile engineering teams have used Crash-Free Session Rate (CFSR) as their primary release quality benchmark.

The flaw with CFSR is structural: it measures process survivability, not user experience.

When a mobile app freezes, the process is still running. When an API call fails and leaves a progress indicator spinning indefinitely, no unhandled exception is thrown. When a user force-closes the app in frustration, the operating system registers a user termination, not a crash.

To your crash logger, that session was a victory. To your user, it was an infuriating failure.

Deconstructing the Three Horsemen of Silent Decay​

To eliminate silent failures, engineering teams must understand the three distinct technical mechanisms that cause them:

1. Android ANRs (Application Not Responding)​

On Android, the operating system monitors UI responsiveness via the system server. If your application cannot process input events or lifecycle callbacks within designated timeframes, Android displays the dreaded Application Not Responding (ANR) dialog:

app is not responding

Close app
Wait

What Triggers an ANR?​

  • Input Dispatching Timeout: The app fails to respond to an input event (e.g., key press or screen touch) within 5 seconds.
  • BroadcastReceiver Timeout: A BroadcastReceiver fails to finish executing within 10 seconds in foreground mode.
  • Service Execution Timeout: A Service executed by the foreground app fails to complete its lifecycle tasks within 20 seconds.

The Business Penalty: Google Play Vitals​

Google Play monitors your app's User-Perceived ANR Rate (ANRs occurring when your app is in the foreground). If your ANR rate exceeds Google's bad behavior threshold of 0.47% overall (or 8% on specific phone models):

  • Google demotes your app in Play Store search rankings.
  • Your app is disqualified from store featuring and promotional carousels.
  • Google Play displays a warning directly on your store listing: "Recent data shows that this app may stop working on your device."

2. iOS App Hangs​

iOS does not display an ANR dialog. Instead, when the main run loop is blocked, the interface simply stops accepting touch input. Tapping buttons produces no ripple effect, scrolling locks up, and animations stutter to a halt.

What Triggers an App Hang?​

The iOS main thread operates as an event run loop (CFRunLoop). When an operation performs synchronous disk I/O, heavy computation, or waits on a dispatch semaphore on the main thread, the run loop cannot process new touch events.

  • Micro-Hangs (250ms – 500ms): Perceived by users as "jank," dropped frames, or sluggishness.
  • Severe Hangs (> 2,000ms): Users perceive the app as completely frozen. Over 70% of users will force-quit an app if an interaction takes longer than 3 seconds without visual feedback.

Apple Xcode Organizer Telemetry​

Apple tracks your Hang Rate (measured as milliseconds of hang time per hour of active use). High hang rates directly suppress your visibility in App Store search results and elevate user churn.

3. Silent Functional Failures & Swallowed Exceptions​

Unlike ANRs and App Hangs, silent functional failures often involve zero thread contention. Instead, they are caused by defensive programming gone wrong:

// The Classic "Silent Killer" Pattern:
try {
val response = paymentApi.confirmPurchase(orderId)
updateUiWithReceipt(response)
} catch (e: Exception) {
// Exception caught and logged to console or an unmonitored analytics tag
Log.e("Payment", "Purchase failed", e)
// The spinner continues to animate, or the screen never transitions!
}

The network request times out, or the backend returns a 503 Service Unavailable. Because the exception was caught, no crash occurred. But the user is left looking at an unresponsive checkout button. They tap it three more times, get no feedback, and leave your app forever.

Why Traditional APMs Fail to Diagnose ANRs and Hangs​

Most engineering teams rely on crash loggers to debug ANRs. When an ANR occurs, these tools capture a point-in-time thread dump. But in production, these thread dumps are notoriously misleading:

1. The "Innocent Bystander" Stack Trace​

When an operating system triggers an ANR dump at second 5, the thread dump records whatever code happens to be executing at that exact millisecond. Frequently, this is an innocent operating system wait call:

"main" prio=5 tid=1 Native
#00 pc 000000000004b344 /apex/com.android.runtime/lib64/bionic/libc.so (syscall+28)
#01 pc 00000000001ae4f8 /apex/com.android.art/lib64/libart.so (art::ConditionVariable::WaitHoldingLocks)

The stack trace tells you the main thread is waiting for a lock. But which thread holds the lock? And what action caused the lock to be acquired in the first place? The thread dump cannot answer either question.

2. Lack of Preceding User Interaction Context​

Did the user tap a filter button? Did they background the app and return? Did their network connection drop from Wi-Fi to cellular right before the freeze? Standard thread dumps provide zero historical sequence.

3. No Correlation to Business Impact​

If an ANR occurs during app startup on an obsolete Android 8 device, it is an annoyance. If an App Hang occurs every time a high-value customer taps "Complete Purchase" on iOS 18, it is a business catastrophe. Traditional tools treat both events as isolated technical entries.

How Appxiom Solves Silent Failures: Continuous Forensics​

Appxiom tackles silent failures by bridging the gap between technical thread execution and user experience:

1. Proactive Main-Thread Watchdogs​

Appxiom continuously monitors UI thread responsiveness and runloop latency. If a task stalls the UI thread for longer than your defined threshold, Appxiom captures the event before the user force-closes the application.

2. The Activity Trail: Reconstructing the Crime Scene​

Instead of an isolated thread dump, Appxiom attaches the complete Activity Trail to every ANR and App Hang report:

APPXIOM ANR REPORT

Issue: ANR Detected (Main thread blocked for 5,240ms)
Version: v3.4.1 (Build 92)  |  Device: Samsung Galaxy S23  |  OS: Android 14

TIME

TYPE

DETAILS

FREE MEM

14:10:02.115LIFECYCLEOrdersActivity:onResume52.1%
14:10:03.450USER ACTIONClicked "Sync Offline Orders"51.8%
14:10:03.480CUSTOMlocal_db_query_started51.8%
14:10:03.490HTTPPOST /api/v2/orders/sync → 200 OK (310ms)51.2%
14:10:03.810CUSTOMparsing_5000_json_items49.5%
14:10:08.730ISSUE

ANR: Main thread stalled during JSON parsing for 5,240ms

48.9%

What this tells the engineer:​

In 15 seconds, the developer sees what happened:

  1. The user tapped 'Sync Offline Orders'.
  2. The network request succeeded quickly (200 OK in 310ms).
  3. The response contained 5,000 JSON items.
  4. The JSON parsing and database insertion were executed synchronously on the main thread instead of offloaded to a background coroutine or thread pool.
  5. The UI froze for 5.2 seconds, triggering the ANR.

3. Goal Friction Impact (GFI)​

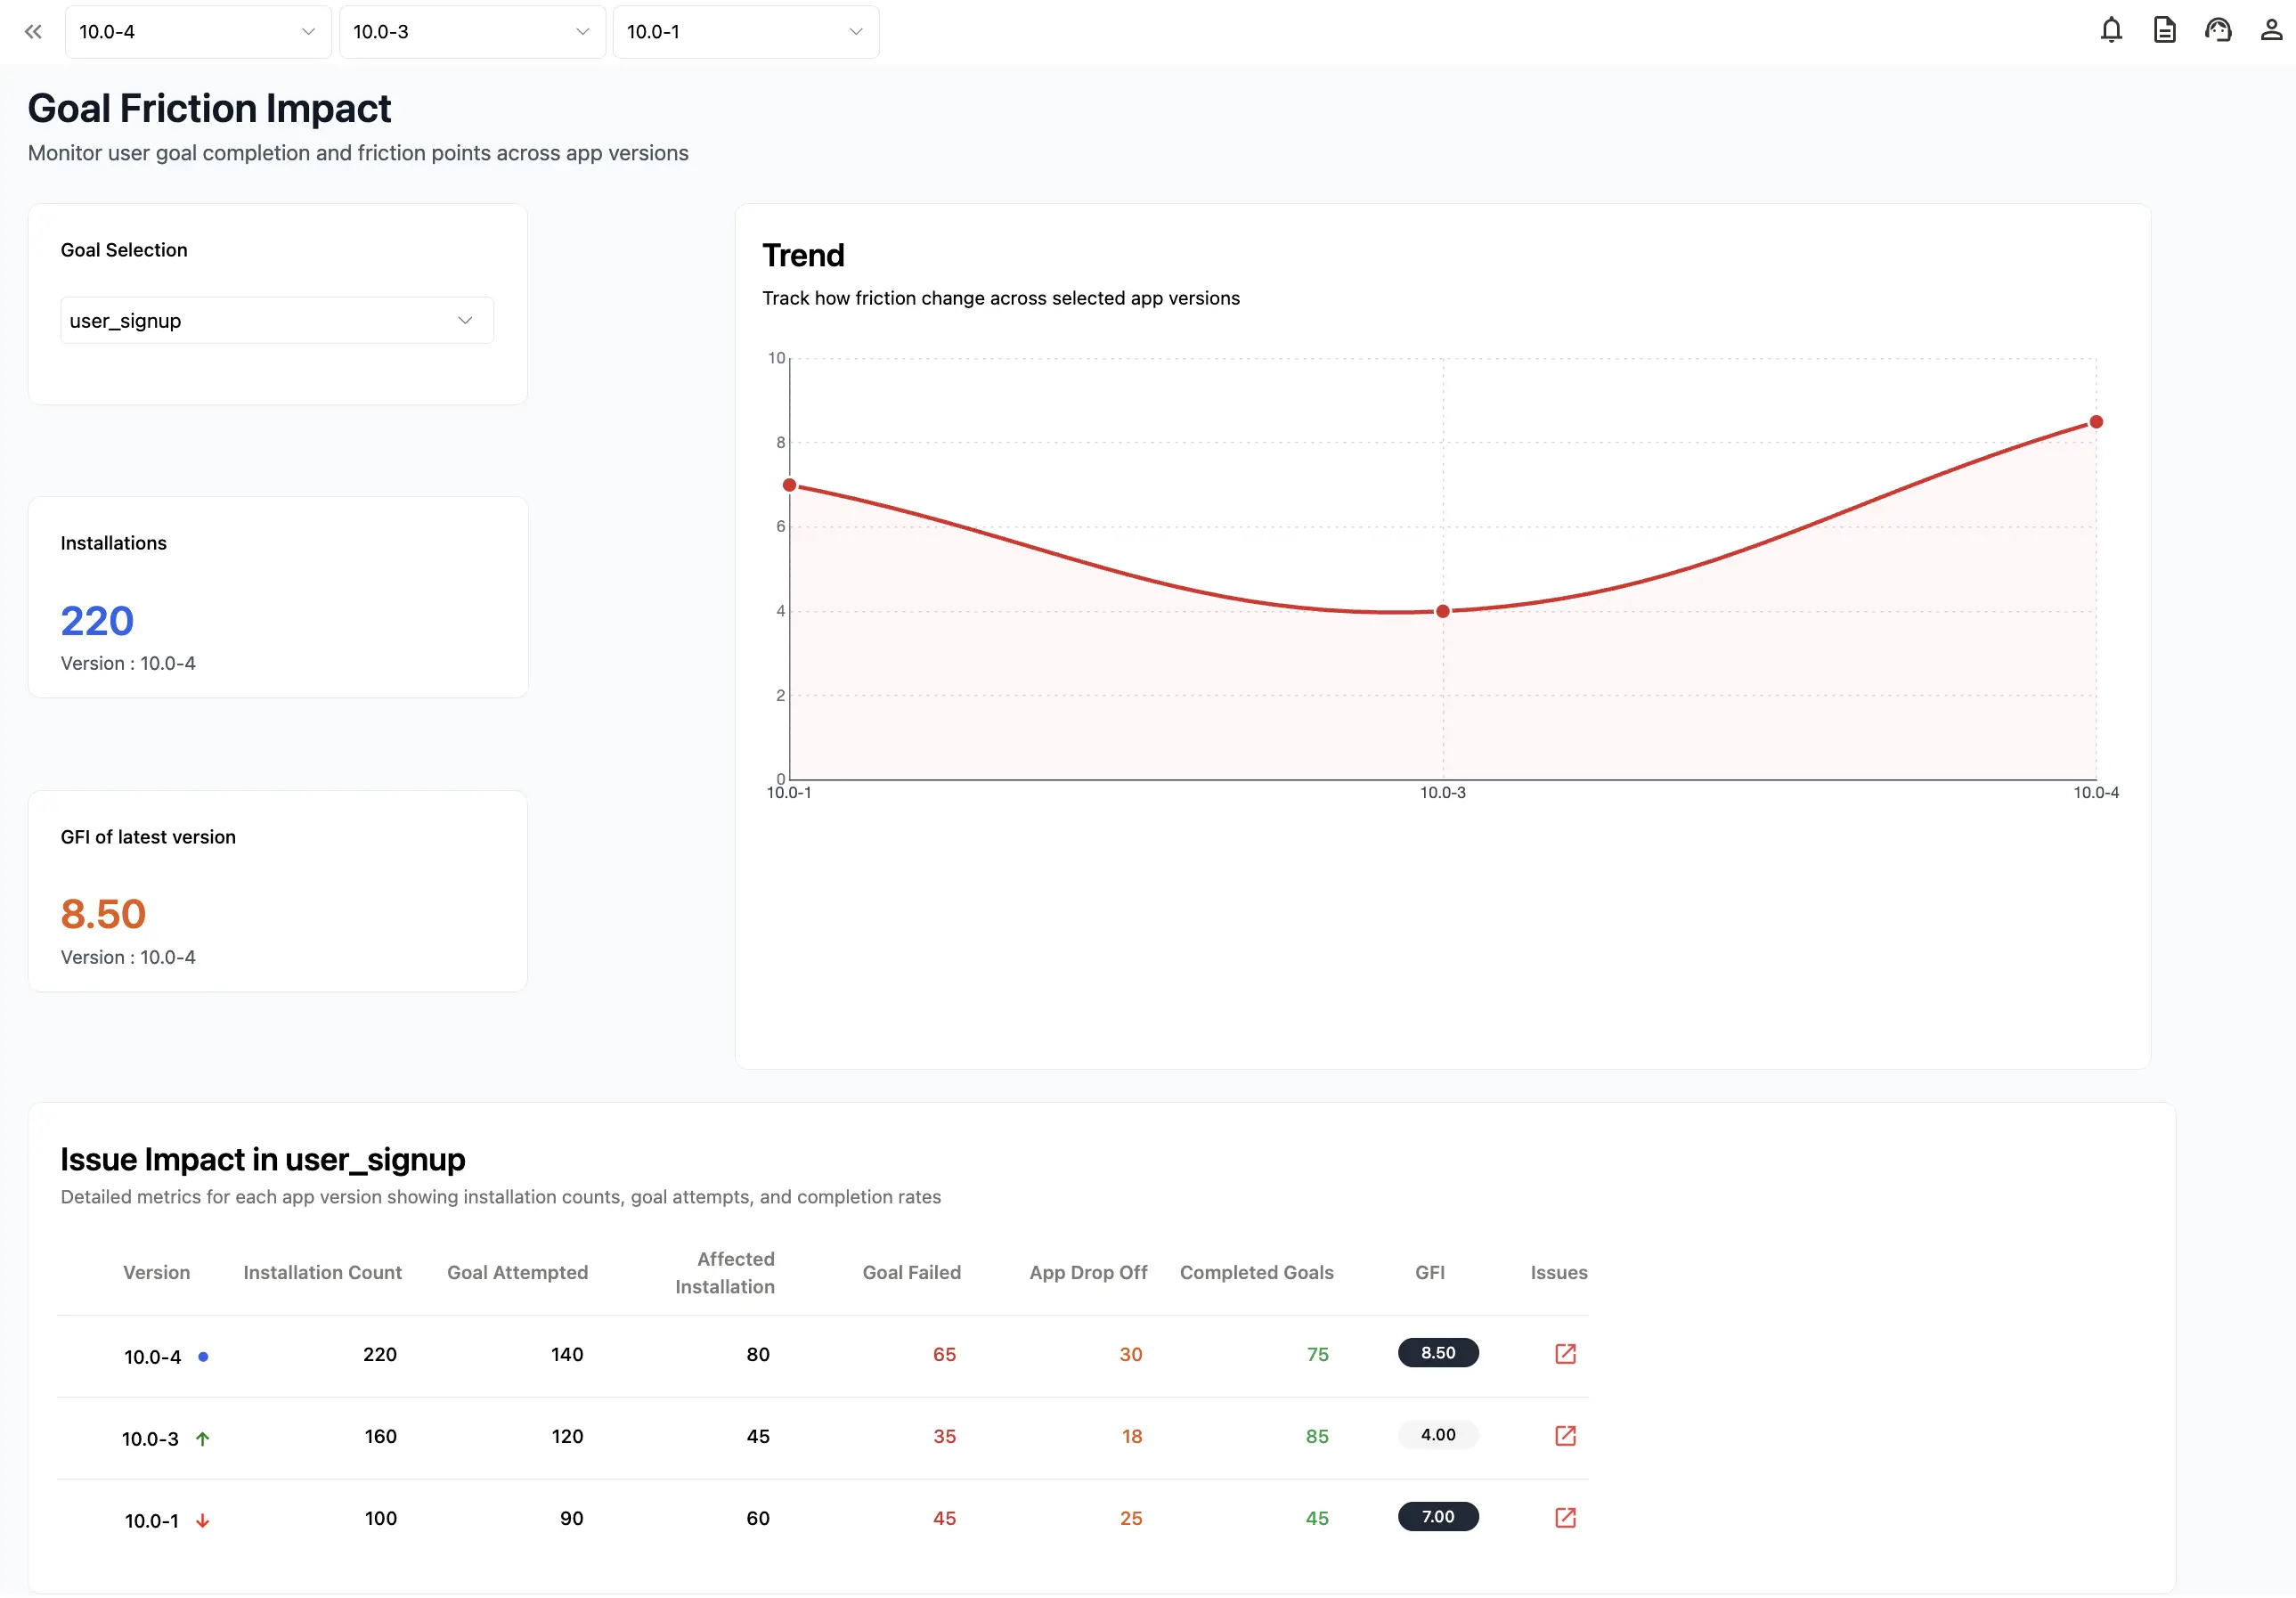
Through Goal Friction Impact, Appxiom correlates silent ANRs and hangs directly to user drop-offs in critical funnels (such as checkout, signup, or subscription).

If a silent freeze occurs in a settings menu, its GFI score is low (e.g., 1.2/10). If an App Hang occurs during credit card validation, its GFI spikes to 9.6/10, immediately alerting your team to a revenue-critical blocker.

4. Appxiom Quality Score (QS)​

Unlike binary crash-free rates, the Appxiom Quality Score evaluates version health on a unified 0–10 scale that penalizes ANRs, App Hangs, and slow screen loads alongside fatal crashes.

Technical Best Practices: Preventing Main-Thread Freezes​

Eliminating ANRs and App Hangs requires architectural discipline across your codebase. Here are the core patterns to enforce:

Android: Moving Work Off the Main Thread​

1. Enforce Background Dispatchers for I/O​

Never perform disk reads, SharedPreferences writes, Room queries, or network operations on Dispatchers.Main:

// BAD: Runs on Main Thread, causes ANR under heavy DB load
fun loadUserTransactions() {
val transactions = database.transactionDao().getAll() // BLOCKS UI THREAD
updateUi(transactions)
}

// GOOD: Offloaded to Dispatchers.IO with Kotlin Coroutines
fun loadUserTransactions() = viewModelScope.launch {
val transactions = withContext(Dispatchers.IO) {
database.transactionDao().getAll()
}
updateUi(transactions)
}

2. Enable StrictMode in Debug Builds​

Catch disk and network violations during development before they ever reach production:

if (BuildConfig.DEBUG) {
StrictMode.setThreadPolicy(
StrictMode.ThreadPolicy.Builder()
.detectDiskReads()
.detectDiskWrites()
.detectNetwork()
.penaltyLog()
.build()
)
}

iOS: Eliminating Runloop Blocking in Swift​

1. Leverage Swift 6 Concurrency & Actor Isolation​

Ensure heavy computations are decoupled from the @MainActor:

// BAD: Synchronous heavy parsing on the main actor
@MainActor
func processOrderHistory(data: Data) {
let decoder = JSONDecoder()
// Heavy JSON parsing locks the main runloop
let orders = try? decoder.decode([Order].self, from: data)
self.displayOrders(orders)
}

// GOOD: Background task processing
@MainActor
func processOrderHistory(data: Data) async {
let orders = await Task.detached(priority: .userInitiated) {
let decoder = JSONDecoder()
return try? decoder.decode([Order].self, from: data)
}.value

self.displayOrders(orders)
}

2. Avoid Synchronous Semaphore Waits on the Main Queue​

Never call dispatch_semaphore_wait or DispatchGroup.wait() on the main thread while waiting for a background completion handler. If the background thread requires main-thread access to complete, your app enters an immediate deadlock.

Flutter: Isolates for Heavy Computation​

In Flutter, the Dart engine runs on a single event loop. If you perform heavy operations on that loop, you freeze the UI across both Android and iOS simultaneously:

// BAD: Blocks Flutter root isolate
void parseLargeJson(String rawJson) {
final data = jsonDecode(rawJson); // Drops frames or triggers ANR
setState(() => items = data);
}

// GOOD: Offload to background Isolate using compute()
Future<void> parseLargeJson(String rawJson) async {
final data = await compute(jsonDecode, rawJson);
setState(() => items = data);
}

Comparison: Fatal Crash Monitoring vs. Appxiom Observability​

CapabilityTraditional Crash Loggers (Crashlytics, Bugsnag)Appxiom Performance & Error Platform
Fatal Exception Tracking✅ Yes✅ Yes
Android ANR Detection⚠️ Post-mortem thread dumps only✅ Real-time watchdog + Activity Trail
iOS App Hang Detection❌ Limited or omitted✅ Micro-hang & severe hang tracking
Silent API & State Failures❌ Omitted (process stays alive)✅ Automatic 4xx/5xx & flow block detection
User Interaction Footsteps❌ Generic breadcrumbs✅ Auto-tracked taps, gestures & lifecycles
Business Impact Metric❌ Occurrence count only✅ Goal Friction Impact (0–10 GFI Score)
Holistic Version Quality❌ Binary Crash-Free Rate✅ Appxiom Quality Score (0–10 QS)

The End of Invisible Bugs​

A crash that affects 10 users in an obscure background service is easy to spot on your dashboard.

An App Hang that freezes 5,000 customers during checkout is far more devastating—yet traditional monitoring platforms let it slip by in complete silence.

Stop relying on vanity metrics that disguise broken user experiences as healthy releases.

With Appxiom, you detect the failures that matter most:

  • Pinpoint the exact line of code causing your ANRs and App Hangs.
  • Retrace the user footsteps that led to the freeze.
  • Protect your App Store rankings and Google Play Vitals.
  • Fix release regressions before they cost you revenue.

Stop Letting Silent Failures Drain Your Revenue​

See how Appxiom gives mobile engineering teams the clarity they need to eliminate ANRs, App Hangs, and invisible regressions.

Start Your Free Appxiom Trial Today or explore our types of bugs detected in mobile and web apps.
Stop Guessing 'How to Reproduce': Debugging Release Regressions with Appxiom's Activity Trail

Published: · 17 min read
Andrea Sunny
Marketing Associate, Appxiom

You just shipped version v4.2.0 of your mobile application. Every unit test passed in CI, staging looked rock-solid, and the release train left the station on schedule.

Twenty-four hours later, the Slack notifications start pouring in.

Customer support is escalating tickets. App Store reviews are dropping from 4.8 to 3.2 stars. Product managers are asking why checkout conversion dropped by 18%. And on Jira, you are assigned a ticket titled:

"App crashes or freezes when user tries to place an order after applying coupon."
Steps to Reproduce: "Unknown. Just tap around in the cart."

You pull up your error tracker - Firebase Crashlytics, Sentry, or Bugsnag. You find the stack trace:

Fatal Exception: java.lang.IllegalStateException: 
Can not perform this action after onSaveInstanceState
at androidx.fragment.app.FragmentManager.checkStateLoss(FragmentManager.java:1844)
at androidx.fragment.app.FragmentManager.enqueueAction(FragmentManager.java:1884)
at androidx.fragment.app.BackStackRecord.commitInternal(BackStackRecord.java:329)
at com.example.store.checkout.CheckoutFragment.showOrderConfirmation(CheckoutFragment.kt:342)

You open the codebase. You launch the emulator on your workstation. You add an item to the cart, apply a coupon, tap checkout, and... it works completely fine.

You test it on five different test devices. It works fine on every single one.

You reply to the ticket: "Unable to reproduce locally. Need more info." QA replies: "We saw it twice on staging, but can't replicate it consistently." Support asks the customer for a screen recording. The customer ignores the email and uninstalls the app.

Welcome to the most demoralizing, soul-crushing ritual in modern software engineering: debugging production release regressions without knowing what the user actually did.

Why Stack Traces Fail: The Point-of-Impact Fallacy in Production Regressions​

For the past fifteen years, engineering teams have relied on stack traces as the primary source of truth for software defects. But mobile applications have evolved into complex, asynchronous, multi-threaded state machines.

When an issue occurs in production, a stack trace only tells you where the process failed (the point of impact). It tells you virtually nothing about the sequence of events that created the corrupted state (the crime scene).

Traditional Crash ReportingVisibility / Details
Point-of-Impact Stack TraceLine 342 in CheckoutFragment
"What broke?"IllegalStateException
"What was the user doing 5 seconds before?"❓ Unknown
"Which buttons were tapped?"❓ Unknown
"Did the network drop or switch?"❓ Unknown
"Was the app backgrounded and restored?"❓ Unknown

Consider the typical root causes of production release regressions that make them so notoriously hard to reproduce:

1. Asynchronous Race Conditions & Network Latency Spikes​

The user taps a button while an HTTP request is still in flight. A fast 5G connection in your office resolves the promise in 80 milliseconds. But a user on a commuter train with fluctuating 4G encounters a 1,800-millisecond latency spike. During that delay, they tap the button a second time, background the app to check an SMS verification code, and return. The response arrives when the UI fragment is already detached. The crash happens in an Android lifecycle callback, but the root cause was the unhandled button re-tap during a cellular latency spike.

2. Silent Failures, ANRs, and UI Freezes (App Hangs)​

A staggering percentage of release regressions never generate a fatal exception.

  • Android ANRs (Application Not Responding): The main thread stalls on disk I/O, lock contention, or heavy computation for more than 5 seconds.
  • iOS App Hangs: The main run loop blocks, rendering touch targets completely unresponsive.
  • Network Dead-Ends: An API responds with a 404 or 500 error that was swallowed in a generic try/catch block, leaving the loading spinner spinning indefinitely.

Because the operating system didn't terminate the process with a fatal signal, traditional crash loggers record either nothing or an unhelpful system thread dump that points to an idle OS loop.

3. The Breadcrumb Noise Problem​

Some APM tools attempt to capture "breadcrumbs," but they typically suffer from two extremes:

  • The Firehose: Millions of unindexed log lines that pollute dashboards, cost a fortune in ingestion fees, and drown engineers in useless console chatter.
  • The Desert: Generic system events like Activity Resumed without details on button clicks, touch targets, memory pressure, or offline state changes.

When a regression strikes, engineers don't need a million lines of unstructured text. They need a clean, chronological flight recorder that reconstructs the exact user footsteps prior to the failure.

What is Appxiom's Activity Trail? The Black Box Flight Recorder for Apps​

Appxiom was engineered to eliminate the "Cannot Reproduce" ticket entirely.

At the heart of Appxiom's diagnostic engine is the Activity Trail: a chronologically ordered, high-fidelity timeline of events, user interactions, lifecycle shifts, and network state changes captured immediately prior to any issue occurrence.

[!NOTE] What is an Activity Trail?
An Activity Trail is a chronologically ordered, microsecond-accurate timeline of user interactions (taps, clicks, gestures), screen and component lifecycle transitions, network connectivity changes, and custom developer markers captured immediately prior to an issue occurrence. It enables engineers to retrace exact user steps and reproduce release regressions without guesswork or screen recordings.

When an issue occurs - whether it is an uncaught exception, a memory leak, an ANR, an iOS App Hang, or an API failure - Appxiom packages the stack trace together with the preceding Activity Trail.

Developers and QA teams can open the issue report in the Appxiom dashboard and immediately inspect the exact breadcrumb trail leading up to the failure.

The Four Pillars of the Activity Trail​

Unlike ad-hoc logging solutions that require writing boilerplate logging statements across every view, the Activity Trail is built on four automated capabilities:

1. Auto-Tracked User Interactions​

Appxiom automatically captures UI touch events - clicks, taps, button presses, and gestures - without requiring developers to manually bind click listeners or insert logging hooks.

When a customer encounters a regression, you don't have to wonder whether they tapped "Submit", "Cancel", or the back arrow. The Activity Trail explicitly records:

  • App:TextButton - 'view order' tapped
  • App:ElevatedButton - 'Get Location' tapped
  • App:ElevatedButton - 'Place Order' tapped

2. Screen Navigation & Lifecycle Transitions​

Mobile state corruption almost always stems from screen transitions and lifecycle changes. Appxiom automatically records:

  • Activity and Fragment lifecycle events in Android (onCreate, onStart, onResume, onPause, onDestroy).
  • UIViewController lifecycle events in iOS (viewDidLoad, viewWillAppear, viewDidAppear).
  • Widget and component mounts in Flutter and React Native.
  • Foreground/background transitions (e.g., when the user switches apps or locks their screen).

3. Environment & Network State Changes​

Network connectivity on mobile devices is inherently unstable. Appxiom monitors device connectivity state changes and captures:

  • When the device drops from Wi-Fi to Cellular or goes completely offline.
  • When connectivity is restored.
  • Outgoing HTTP and HTTPS requests, including target endpoints, HTTP methods, latency in milliseconds, and status codes (e.g., 200 OK (86ms) or 404 Not Found (142ms)).

4. Custom Developer Markers (Ax.setActivityMarker)​

While auto-tracking captures the technical and UI baseline, developers often need to stamp domain-specific business context into the trail.

Appxiom provides a clean, single-line API that can be called anywhere in your codebase:

// Android (Kotlin)
Ax.setActivityMarker(this@CheckoutActivity, "checkout_step_coupon_applied: SUMMER26")
// iOS (Swift)
Ax.setActivityMarkerAt(self, marker: "biometric_authentication_verified")
// Flutter
Ax.setActivityMarker("cart_recalculated_with_tax: $total");

These custom markers are woven directly into the chronological stream alongside taps, screen transitions, and HTTP calls.

Activity Trail vs. Heavy Session Replay: Why Lightweight Breadcrumbs Win​

A common question engineers ask is: "Why not just use a full session replay tool like LogRocket, FullStory, or Sentry Session Replay?"

While session replay video recordings sound appealing on paper, engineering teams frequently abandon them in mobile production for several critical reasons:

Feature / ConsiderationHeavy Session Replay ToolsAppxiom Activity Trail
CPU & Frame Rate ImpactHigh (captures DOM/Canvas frames, causes UI jank)Zero (idle-frame execution, smooth 60/120fps)
Network & Battery DrainHeavy (megabytes of compressed video/wireframes)Negligible (ultra-compressed text payloads)
Data Privacy & PII RiskHigh risk of leaking passwords, cards, or user dataZero PII by design (captures events, not inputs)
Offline ResilienceBuffers fail or drop video chunks on bad networksSandboxed local cache with seamless resend
Engineering SignalRequires watching 5-minute videos to find a bugInstant 10-second scan of the exact causal chain

Activity Trail gives developers the precise technical forensics they need to fix code without the privacy nightmares, compliance headaches, or performance penalties of video replays.

Visualizing the Crime Scene: Chronological Activity Trail Walkthrough​

Below is an example of what an engineer sees in the Appxiom dashboard when inspecting an issue report. Notice how each event includes a microsecond-accurate timestamp, event category, event payload, and the device's free memory percentage at that exact moment:

APPXIOM ACTIVITY TRAIL TIMELINE

Issue: POST /api/v2/orders/process → 409 Conflict
Exception: IllegalStateException: Order already locked
Version: v4.2.0 (Build 184) | Device: Google Pixel 8 | OS: Android 15

TIMECATEGORYEVENT DETAILSFREE MEM
10:14:02.115LIFECYCLECartActivity:onResume48.2%
10:14:03.450USER ACTIONClicked "Apply Promo Code"48.0%
10:14:03.538HTTPPOST /api/v2/promos/validate → 200 OK (88ms)47.9%
10:14:04.102CUSTOMAx.setActivityMarker: promo_applied_SUMMER2647.9%
10:14:06.890USER ACTIONClicked "Proceed to Checkout"47.5%
10:14:07.012LIFECYCLECheckoutActivity:onCreate46.8%
10:14:07.410LIFECYCLECheckoutActivity:onResume46.8%
10:14:08.115NETWORKWIFI → CELLULAR_OFFLINE46.8%
10:14:08.840USER ACTIONClicked "Place Order" (Tap 1)46.5%
10:14:09.120USER ACTIONClicked "Place Order" (Tap 2)46.5%
10:14:09.650NETWORKCELLULAR_OFFLINE → 4G_ONLINE46.4%
10:14:10.200HTTPPOST /api/v2/orders/process → 200 OK (110ms)46.2%
10:14:10.315HTTPPOST /api/v2/orders/process → 409 Conflict (98ms)46.2%
10:14:10.420ISSUEIllegalStateException: Cannot process duplicate46.1%

Dissecting the Crime Scene in Under 60 Seconds​

Without the Activity Trail, all the engineer would see is a stack trace showing IllegalStateException: Cannot process duplicate order at CheckoutActivity.kt:188.

The engineer would spend days trying to understand why duplicate orders are being sent. Is the backend caching stale idempotency tokens? Is Retrofit duplicating headers?

With the Activity Trail, the answer is immediately obvious:

  1. At 10:14:08.115, the user's connection dropped to offline.
  2. The user tapped 'Place Order'. Nothing visibly happened because the request was queued.
  3. Frustrated, the user tapped 'Place Order' a second time at 10:14:09.120.
  4. Half a second later, network connectivity was restored.
  5. Both queued requests fired simultaneously. The first succeeded (200 OK), but the second was rejected by the server (409 Conflict).
  6. The client code lacked button debouncing and did not handle the 409 conflict gracefully, triggering an unhandled exception.

Time to diagnose: 45 seconds.
Fix: Add a UI debounce on the checkout button and catch 409 status responses to show an idempotent confirmation banner.

Solving Three Infuriating Release Regressions with Activity Trail​

Let's look at three notorious categories of regressions that plague engineering teams and how Activity Trail resolves them.

Case 1: State Restoration & Race Conditions After App Backgrounding​

The Bug: Users complain that after receiving a phone call or switching to their banking app to copy a one-time password (OTP), returning to your app causes a blank screen or a crash.

Why It's a Nightmare to Reproduce: On developer devices, Android and iOS have ample RAM. When you switch apps during testing, your application remains alive in memory. But in production, users with 20 background apps, low-end devices, or aggressive OEM battery optimizers experience immediate process death.

How Activity Trail Solves It: The trail clearly records:

14:22:10.100  LIFECYCLE    PaymentActivity:onPause
14:22:10.350 LIFECYCLE PaymentActivity:onStop
14:22:10.400 LIFECYCLE App went to BACKGROUND
14:22:35.800 LIFECYCLE App returned to FOREGROUND
14:22:36.100 LIFECYCLE PaymentActivity:onCreate (savedInstanceState != null)
14:22:36.210 ISSUE NullPointerException: ViewModelFactory not initialized

The developer instantly realizes: the activity restoration flow assumed the DI singleton was still warm. When the OS killed the process in the background, onCreate ran with a non-null savedInstanceState, but the singleton was re-initialized to null.

Case 2: Silent ANRs and UI Freezes on the Main Thread​

The Bug: Google Play Console flags a spike in your ANR rate, threatening your app's search visibility and store ranking. The trace provided by Google Play Vitals simply says:

"main" prio=5 tid=1 Native
#00 pc 000000000004b344 /apex/com.android.runtime/lib64/bionic/libc.so (syscall+28)
#01 pc 00000000001ae4f8 /apex/com.android.art/lib64/libart.so (art::ConditionVariable::WaitHoldingLocks)

This tells you the main thread was waiting on a lock. Which lock? Triggered by what? Google Play Vitals cannot tell you.

How Activity Trail Solves It: In Appxiom, the ANR issue report displays the chronological trail right before the freeze:

12:22:50.110  USER ACTION  Clicked - button - 'Filter Transactions'
12:22:50.215 CUSTOM Ax.setActivityMarker: filter_dataset_size_45000_items
12:22:50.220 LIFECYCLE TransactionListFragment:onPause
12:22:55.300 ISSUE ANR Detected: Main thread blocked for 5,080ms

The correlation is unmistakable: the user clicked 'Filter Transactions' with a dataset of 45,000 items. The sorting operation ran synchronously on the main thread instead of being offloaded to Dispatchers.Default or a background worker.

Case 3: Progressive Memory Leaks Disguised as Out-Of-Memory Crashes​

The Bug: You see an OutOfMemory (OOM) crash on a simple profile update screen. Developers insist: "There's no way updating an avatar consumes 512 MB of heap!"

How Activity Trail Solves It: Because Appxiom records the free memory percentage with every single lifecycle event and marker, you can trace the memory trajectory over time:

09:15:10  ProductDetailActivity:onCreate       54.2% FREE MEMORY
09:15:32 ProductDetailActivity:onDestroy 48.1% FREE MEMORY
09:16:04 ProductDetailActivity:onCreate 41.3% FREE MEMORY
09:16:28 ProductDetailActivity:onDestroy 35.0% FREE MEMORY
09:17:02 ProductDetailActivity:onCreate 28.4% FREE MEMORY
09:17:40 ProductDetailActivity:onDestroy 21.1% FREE MEMORY
09:18:12 ProfileActivity:onCreate 12.5% FREE MEMORY
09:18:15 ISSUE: java.lang.OutOfMemoryError 4.1% FREE MEMORY

The profile screen didn't cause the leak. The ProductDetailActivity was failing to unregister an image caching listener, leaking 30 MB of bitmap memory every time it was opened. The profile screen was merely the unlucky innocent bystander when memory ran out.

Instrumenting Activity Trail Across Android, iOS, and Flutter​

Instrumenting your application with Appxiom doesn't require rewriting your codebase. The SDK is engineered for effortless setup and zero friction.

Android (Kotlin & Java)​

import com.appxiom.android.Ax

class CheckoutActivity : AppCompatActivity() {

override fun onCreate(savedInstanceState: Bundle?) {
super.onCreate(savedInstanceState)
setContentView(R.layout.activity_checkout)

// Custom marker that appears in the Activity Trail
Ax.setActivityMarker(this, "entered_checkout_flow")

// Debug-only marker (automatically stripped from release builds)
Ax.setActivityMarkerForDebug(this, "debug_cart_hash: ${cart.hashCode()}")
}
}

ProGuard & R8 Protection: When using aggressive code shrinking and obfuscation, class names in standard crash reports turn into unreadable alphabet soup (a.b.c). Appxiom provides the @AX annotation to maintain human-readable identifiers in your Activity Trail even in release builds:

@AX("CheckoutScreen")
class CheckoutActivity : AppCompatActivity() { ... }

iOS (Swift & SwiftUI)​

import Appxiom

class PaymentViewController: UIViewController {

override fun viewDidLoad() {
super.viewDidLoad()

// Single-line marker injection
Ax.setActivityMarkerAt(self, marker: "stripe_payment_sheet_presented")
}

@IBAction func didTapPayButton(_ sender: UIButton) {
Ax.setActivityMarkerAt(self, marker: "pay_button_pressed")
processPayment()
}
}

Flutter (Dart)​

import 'package:appxiom_flutter/appxiom_flutter.dart';

void main() async {
WidgetsFlutterBinding.ensureInitialized();

// Initialize Appxiom for Android & iOS
Ax.init("android_app_key", "android_platform_key");
Ax.initIOS();

// Wrap app runner for automatic widget and navigation tracking
AxApp.run(
child: const MyApp(),
screenName: 'MainApp',
widgetName: 'MyApp',
);
}

// Anywhere in your business logic:
Ax.setActivityMarker("user_applied_filter_category_electronics");

Production Reliability: Idle-Frame Processing, Offline Sandboxing, and Zero-PII Privacy​

Mobile engineers are rightly skeptical of third-party SDKs that monitor user interactions. If a diagnostic tool causes frame drops or drains the battery, it becomes part of the problem.

Appxiom was designed with three strict production guarantees:

1. Idle-Frame Execution​

Data collection, timestamp calculation, and event buffering run strictly during CPU idle frames. Event batching never interrupts the UI rendering pipeline, ensuring your 60fps and 120fps ProMotion animations remain buttery smooth.

2. Offline Sandbox Buffering​

Mobile users enter tunnels, board subways, and toggle airplane mode. When network connectivity drops, Appxiom securely caches breadcrumbs and activity markers in a local sandbox. Once connectivity is re-established, the data is compressed, batched, and transmitted in the background without dropping a single event.

3. Privacy-First by Design​

Appxiom tracks interaction geometry, button identifiers, and component lifecycles. It never captures sensitive user keystrokes, passwords, or PII. You get the technical context required to reproduce the defect without compromising user privacy or violating GDPR and CCPA compliance.

Beyond Isolated Fixes: Version Analytics, Quality Score, and Release Regression Prevention​

The Activity Trail is a powerful debugging tool for individual bugs, but its true superpower emerges when connected to Appxiom's full observability suite:

  1. Appxiom Quality Score (QS): Evaluates release health on a unified 0–10 scale across crashes, ANRs, app hangs, and latency. If your Quality Score drops immediately after a release, you know a regression has hit production.
  2. Goal Friction Impact (GFI): Quantifies exactly how much money and conversion volume a regression is costing your business by measuring drop-offs in critical funnels (signups, subscriptions, purchases).
  3. Version Analytics: Compares error distributions across releases to verify whether a hotfix genuinely resolved the targeted regression without introducing secondary anomalies.
  4. Activity Trail: Provides the engineering team with the exact user footsteps needed to replicate, diagnose, and fix the root cause immediately.

Instead of arguing in cross-functional meetings about whether a bug is reproducible or how severe it is, engineering, QA, and product teams have a shared, unambiguous timeline of reality.

Stop Guessing. Start Reproducing.​

Every hour your engineering team spends guessing how an edge case happened is an hour stolen from building features that grow your product.

Every ticket closed as "Cannot Reproduce" is a ticking time bomb waiting to detonate in your app store ratings.

With Appxiom's Activity Trail, you never have to ask:

  • "What did the user click before it crashed?"
  • "Can QA get a screen recording?"
  • "Why doesn't this happen on my machine?"

You open the issue, read the trail, and fix the bug.

Ready to Eliminate "Cannot Reproduce" From Your Sprints?​

Stop letting release regressions derail your team's momentum. See how Appxiom's Activity Trail, Quality Score, and Goal Friction Impact give mobile teams superpowers.

Start Your Free Appxiom Trial Today or explore our comprehensive documentation to see how easy integration really is.

App Quality Score (QS): Why Mobile Teams Need More Than Apdex to Measure Release Health

Published: · 11 min read
Andrea Sunny
Marketing Associate, Appxiom

For years, Apdex (Application Performance Index) has been a standard metric for measuring application responsiveness. Popularized by Application Performance Monitoring (APM) platforms, Apdex helps engineering teams understand whether application response times meet predefined performance thresholds. It is an effective indicator of infrastructure and backend performance.

However, mobile app quality extends far beyond response time.

An app can maintain an excellent Apdex score while users still experience crashes, ANRs, frozen screens, memory issues, or UI failures that prevent them from completing important tasks. These problems may not affect server latency, but they significantly impact user experience, release stability, and customer retention.

To bridge this gap, Appxiom introduces Quality Score (QS) - a version-level metric that provides a holistic view of application health by combining signals from crashes, performance issues, stability problems, and other quality indicators into a single score.

Alongside Quality Score, Appxiom also provides Goal Friction Impact (GFI), a complementary metric that measures how technical issues disrupt specific user journeys such as signup, login, checkout, or onboarding.

Together, these metrics help teams answer two equally important questions:

In this article, we'll explore why traditional performance metrics like Apdex are no longer sufficient for evaluating mobile application quality and how Appxiom's Quality Score provides a more complete picture of release health.

Why Apdex Is Necessary - But Not Sufficient for Product Teams​

Apdex measures application responsiveness against a predefined performance threshold (T), helping teams understand whether users experience acceptable response times.

It classifies requests into three categories:

  • "Satisfied:" Response time ≤ T
  • "Tolerating:" T < Response time ≤ 4T
  • "Frustrated:" Response time > 4T or request failures

For infrastructure and backend monitoring, this works extremely well.

What Apdex Measures Effectively​

Apdex provides valuable insights into system performance, including:

  • Backend and API response times
  • Infrastructure latency
  • Service availability
  • Performance regressions
  • SLA and SLO compliance

These metrics help engineering teams identify slow services and maintain application responsiveness.

What Apdex Doesn't Measure​

While response time is important, it represents only one aspect of application quality.

Modern mobile applications frequently experience issues that have little or no impact on server latency but significantly affect user experience.

Examples include:

  • Application crashes
  • ANRs (Application Not Responding)
  • App hangs
  • Frozen frames
  • Memory-related issues
  • UI rendering problems
  • Broken user interactions
  • Startup failures

A payment screen may load instantly but crash when the user taps Pay.

A signup form may respond within milliseconds but fail because of an unexpected client-side validation error.

An application may achieve an excellent Apdex score while users continue abandoning critical workflows due to stability and usability issues.

These problems directly affect application quality, even though traditional performance metrics report everything as healthy.

This is where version-level quality metrics become essential.

The Business Blind Spot: When Apdex Is Green but Application Quality Is Declining​

Consider a typical mobile application after a new release:

  • Weekly Active Users: 500,000
  • Apdex Score: 0.96 (Excellent)
  • 95th Percentile API Response Time: 180 ms
  • Server Availability: 99.98%
  • Infrastructure Alerts: 0

From an infrastructure perspective, the release looks nearly perfect.

But here's what users are actually experiencing:

  • 3,200 users encountered app crashes.
  • 1,850 users experienced ANRs while opening key screens.
  • 4,700 users faced frozen frames and UI responsiveness issues.
  • 2,100 users couldn't complete onboarding because of a client-side validation bug.
  • 1,400 users abandoned checkout after a payment screen failure.

In total, more than 13,000 users experienced quality issues - even though Apdex reported an excellent score.

Traditional performance metrics don't capture these client-side failures because response times remain within acceptable limits. As a result, engineering teams may assume a release is healthy while application quality steadily declines across real user devices.

This disconnect becomes even more significant as applications expand across multiple operating systems, device models, and release versions. Infrastructure metrics reveal how quickly systems respond, but they don't indicate whether a release is becoming more stable - or introducing new quality issues.

This is where Appxiom Quality Score (QS) fills the gap. By continuously evaluating the health of every app version, Quality Score enables teams to compare releases, detect quality regressions early, and understand whether application stability is improving over time.

While Quality Score provides the overall health of a release, Goal Friction Impact (GFI) complements it by identifying how those technical issues affect critical user journeys such as signup, login, onboarding, and checkout.

Together, they provide a complete view of both release quality and business impact.

Understanding Appxiom Quality Score (QS)​

As mobile applications become increasingly complex, evaluating release quality requires more than monitoring crashes or response times in isolation. Engineering teams need a single metric that reflects the overall health of every application version.

Appxiom Quality Score (QS) is designed to provide exactly that.

Quality Score is a version-level health metric that continuously evaluates the stability, reliability, and overall quality of an application release. Instead of analyzing individual issues separately, QS combines multiple quality signals into a single score, allowing teams to quickly understand whether an app version is improving or degrading over time.

Rather than asking:

"How many crashes occurred?"

Quality Score answers:

"How healthy is this release compared to previous versions?"

This enables engineering, QA, and product teams to compare releases at a glance and identify quality regressions before they affect a larger percentage of users.

What Contributes to Quality Score?​

Quality Score considers multiple indicators of application health, including:

  • Application crashes
  • ANRs (Application Not Responding)
  • App hangs
  • Frozen frames
  • Memory-related issues
  • UI responsiveness problems
  • Startup failures
  • Network and API issues
  • Other stability and performance indicators

Instead of reviewing each metric independently, Appxiom aggregates these signals into a single Quality Score for every application version.

Why a Single Quality Score Matters​

Without a consolidated quality metric, engineering teams must manually compare crashes, ANRs, frozen frames, memory issues, and startup failures across every release. Quality Score simplifies this process by summarizing overall release health into a single metric, making it easier to identify regressions and prioritize investigation.

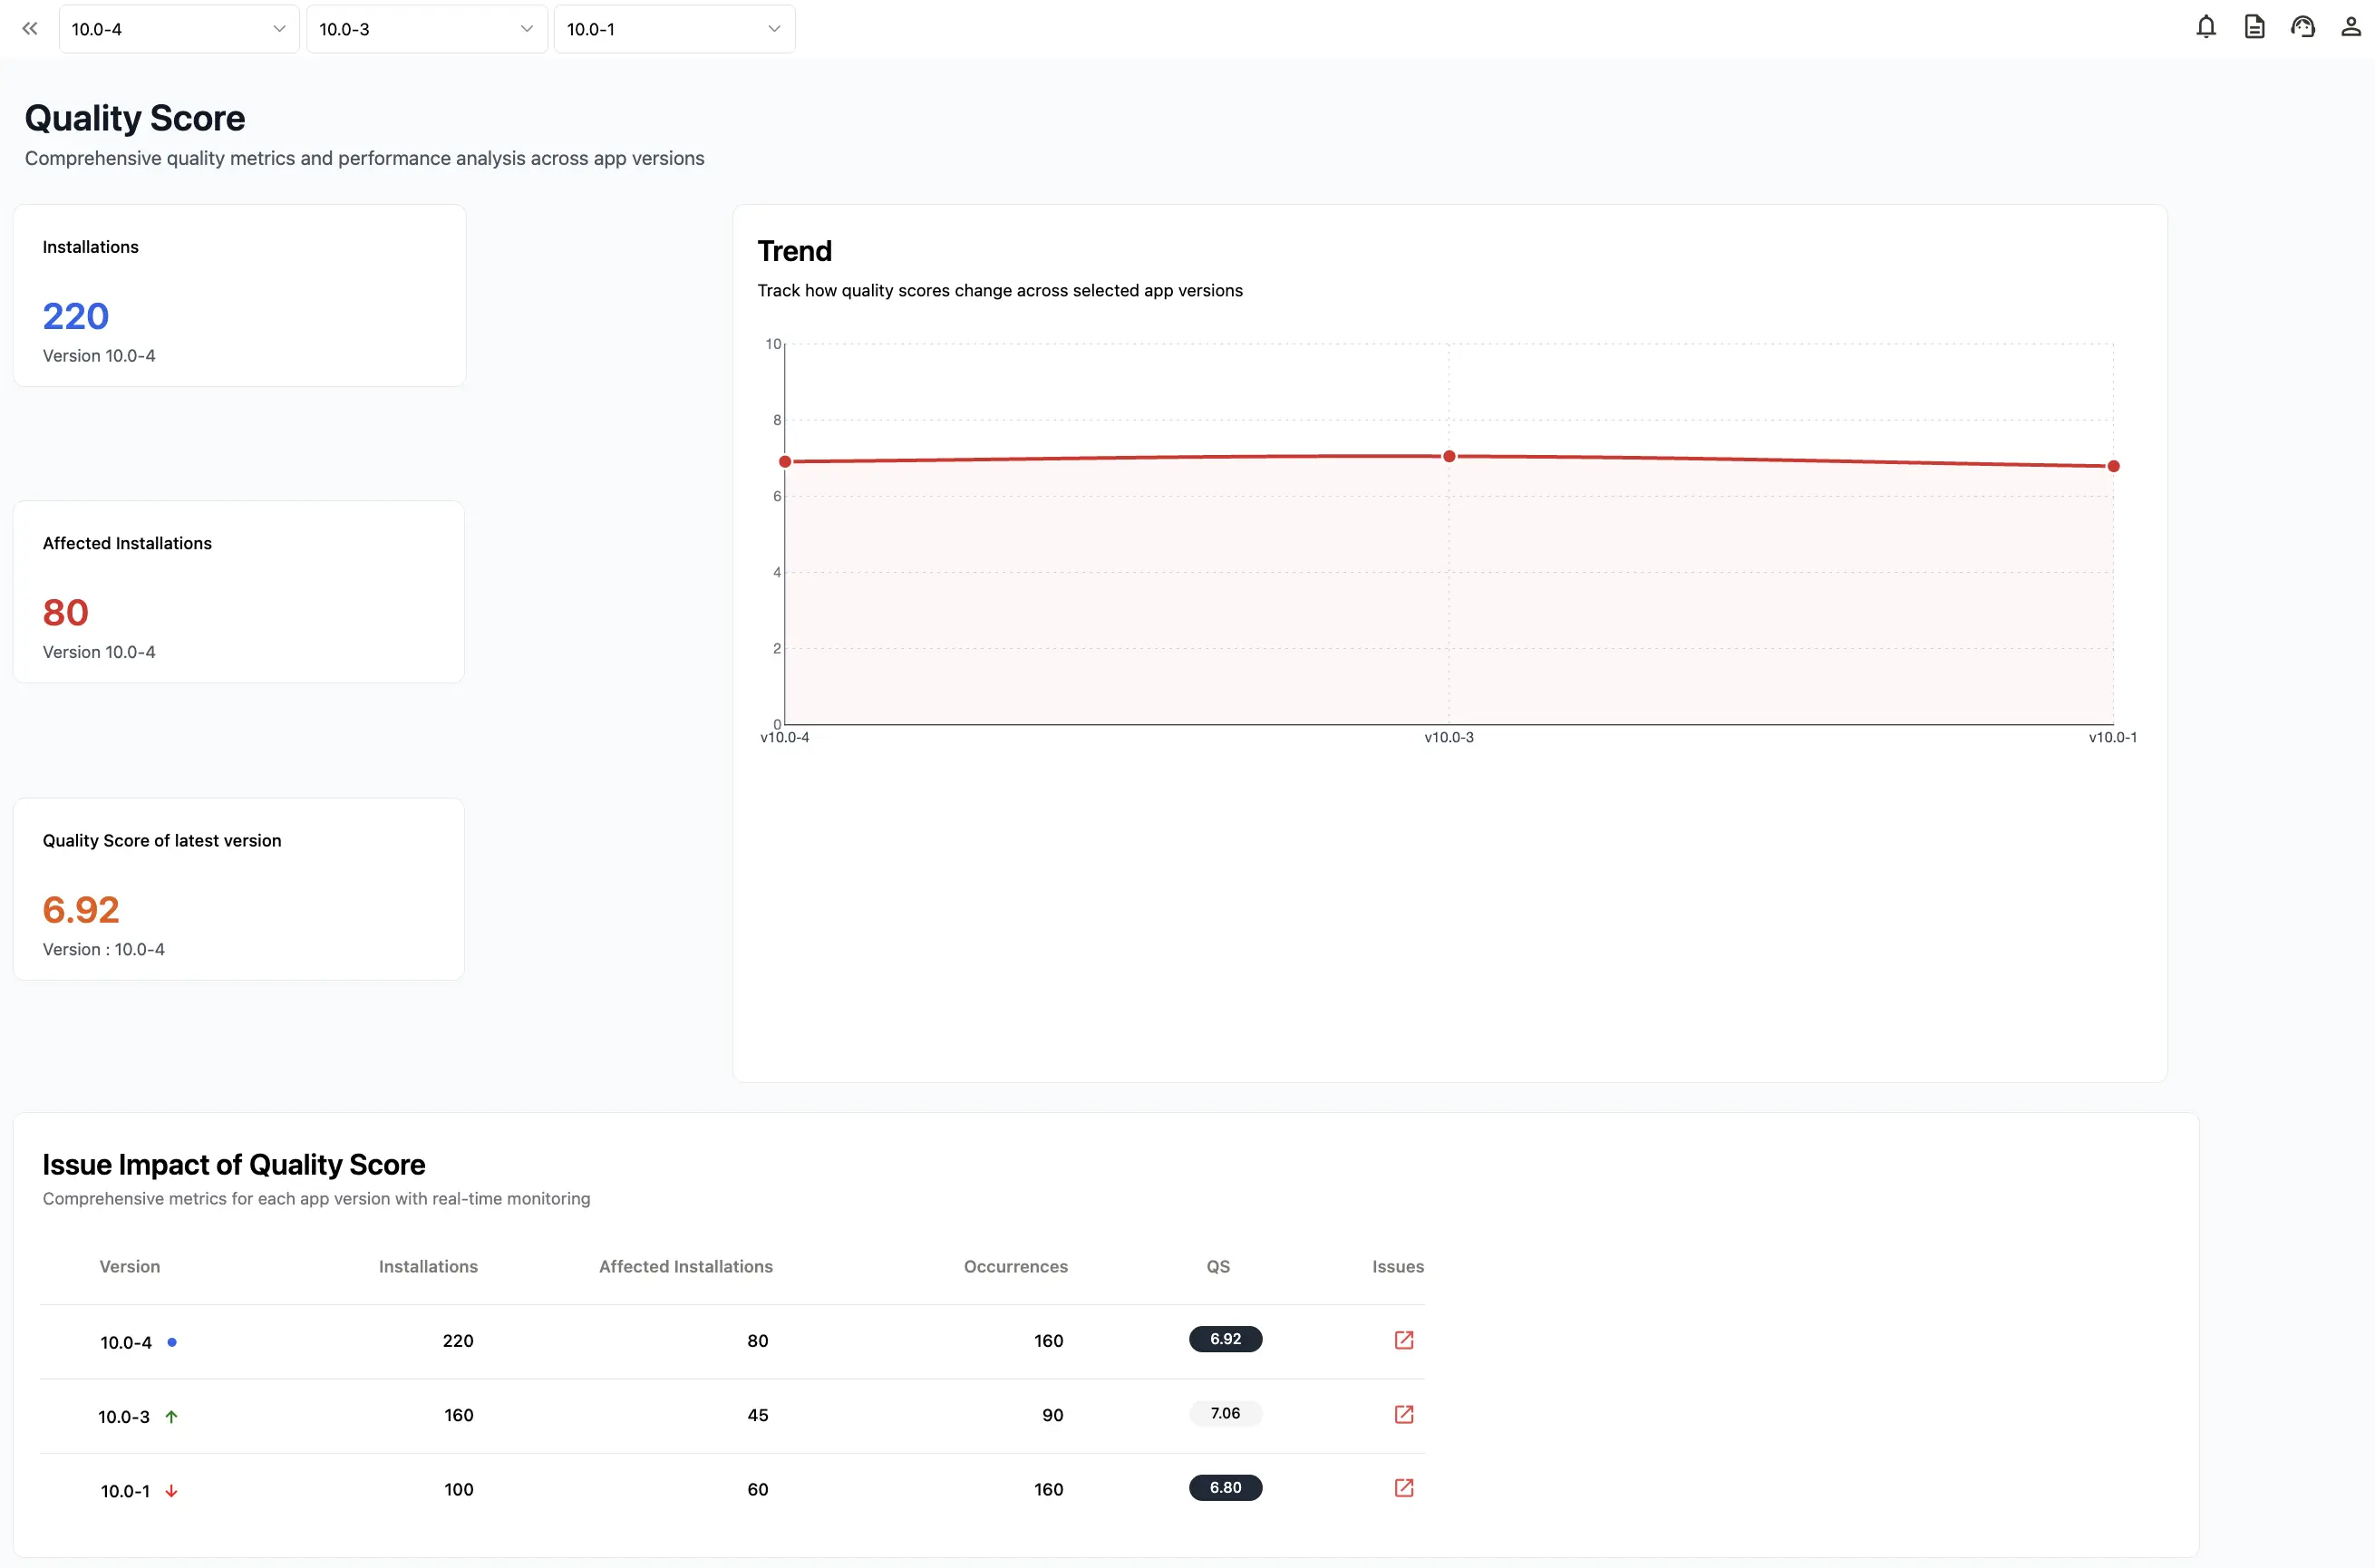
Quality Score Dashboard: Understanding Release Health at a Glance​

One of the biggest challenges in release management is understanding the health of multiple app versions without manually analyzing dozens of performance metrics.

The Appxiom Quality Score Dashboard simplifies this by presenting a consolidated view of every release, allowing engineering and product teams to identify quality trends within seconds.

Instead of reviewing crashes, ANRs, memory issues, and performance metrics separately, teams can immediately compare the quality of every application version using a single score.

The dashboard provides visibility into:

  • Quality Score for every application version
  • Affected Installations experiencing quality issues
  • Total Issue Occurrences detected in each release
  • Historical Quality Score Trends
  • Quick access to issues impacting each version

This enables teams to answer important release questions immediately:

  • Which release is currently the healthiest?
  • Did application quality improve after the latest deployment?
  • Which version introduced the highest number of quality issues?
  • Which release should be prioritized for investigation?

Instead of spending hours correlating multiple dashboards, teams can quickly identify release regressions and focus on the versions that require immediate attention.

Appxiom Quality Score Dashboard

Example

In the dashboard below, each application version is assigned its own Quality Score, along with the number of affected installations and total issue occurrences.

This makes it easy to compare release health over time. A declining Quality Score immediately signals that the latest release may have introduced stability or performance regressions, allowing teams to investigate before issues affect a larger portion of users.

Quality Score vs. Apdex vs. Goal Friction Impact​

While Quality Score provides a comprehensive view of release health, it isn't designed to replace traditional performance metrics like Apdex or user journey metrics like Goal Friction Impact (GFI). Each metric answers a different question about your application.

CapabilityApdexQuality Score (QS)Goal Friction Impact (GFI)
Primary FocusInfrastructure performanceOverall application qualityHealth of individual user journeys
ScopeBackend services and APIsEntire application versionSpecific goals like signup, login, checkout
MeasuresResponse time satisfactionStability, reliability, and qualityFriction caused by technical issues during user journeys
Primary UsersDevOps, SREEngineering, QA, ProductProduct Managers, Growth Teams
AnswersIs the system fast?Is this release healthy?Which user journeys are affected the most?

Rather than competing with one another, these metrics work together to provide a complete understanding of application health - from infrastructure performance to release stability and user experience.

How Goal Friction Impact Complements Quality Score​

Appxiom Goal Friction Impact Dashboard

Quality Score provides a version-level view of application health, making it easy to compare releases and identify stability regressions.

However, even when two releases have similar Quality Scores, the user experience may differ significantly depending on where the issues occur.

For example, a release with minor UI glitches across multiple screens may receive a similar Quality Score to one where a payment failure affects only the checkout journey. While both releases require attention, their business impact is very different.

This is where Goal Friction Impact (GFI) complements Quality Score.

Instead of evaluating the overall health of an application version, GFI focuses on individual user journeys such as signup, login, onboarding, and checkout. It helps teams identify which business-critical goals are experiencing the highest friction, enabling faster prioritization of issues that directly affect user success.

Together, these two metrics provide a more complete view of application quality:

  • Quality Score answers "How healthy is this application release?"
  • Goal Friction Impact answers "Which user journeys are being disrupted?"

By combining both perspectives, engineering and product teams can prioritize fixes based not only on technical severity but also on their impact on the overall release and the user experience.

In our next article, we'll take a deeper dive into Goal Friction Impact (GFI), exploring how it measures friction across user journeys and helps teams prioritize issues based on real business impact.

Release Health: Connecting Code Changes to Usability​

Quality Score becomes even more valuable when tracked across consecutive releases. By comparing scores over time, engineering teams can quickly identify regressions, validate the impact of bug fixes, and measure whether application quality is improving with each deployment. Instead of reviewing dozens of individual metrics after every release, teams can use Quality Score as a consistent benchmark for release health.

Business Benefits of Quality Score​

By monitoring Quality Score, engineering and product teams can:

  • Detect release regressions earlier
  • Compare application quality across versions
  • Validate the impact of bug fixes
  • Improve collaboration between engineering, QA, and product teams
  • Release updates with greater confidence

Quality Score provides a consistent benchmark for measuring application health instead of relying on isolated crash reports or individual performance metrics.

Best Practices for Using Quality Score​

To get the most value from Quality Score:

  • Monitor every release: Track Quality Score after every deployment to identify unexpected regressions early.
  • Compare versions regularly: Review Quality Scores across consecutive releases to measure improvements and validate engineering efforts.
  • Investigate declining scores: A lower Quality Score should prompt deeper analysis into crashes, ANRs, memory issues, and other quality indicators contributing to the decline.
  • Use Quality Score alongside other metrics: Quality Score provides an overall view of release health. Pair it with infrastructure metrics such as Apdex for system performance and Goal Friction Impact (GFI) for understanding how technical issues affect critical user journeys.

Conclusion​

Traditional performance metrics like Apdex remain essential for monitoring infrastructure responsiveness, but they provide only part of the picture. Modern mobile applications require a broader understanding of release quality - one that considers stability, reliability, and the overall user experience.

Appxiom's Quality Score (QS) provides that broader perspective by combining multiple quality indicators into a single version-level metric. Instead of reviewing crashes, ANRs, performance issues, and stability metrics separately, engineering teams can quickly evaluate the health of every application release, compare versions, and identify regressions before they affect more users.

When used alongside infrastructure metrics such as Apdex and complementary insights from Goal Friction Impact (GFI), Quality Score helps engineering and product teams make faster, data-driven release decisions while continuously improving application quality.

If you'd like to explore these metrics in more detail, check out:

Ready to evaluate the quality of your own app?

Sign up for Appxiom and start monitoring your application's release health with Quality Score and Goal Friction Impact. Every new account includes a 30-day free trial, no credit card required, and cancel anytime - so you can explore the platform and see how Appxiom helps you detect, prioritize, and resolve quality issues before they impact your users.

Frame Rate Issues in Flutter Apps and How to Solve Them

Published: · Last updated: · 4 min read
Appxiom Team
Mobile App Performance Experts

Flutter, Google's open-source UI development framework, has gained immense popularity among developers for its cross-platform capabilities and smooth performance. However, like any software development framework, Flutter apps may encounter frame rate issues that can impact user experience.

In this blog, we will explore the common causes of frame rate issues in Flutter apps and provide effective solutions to mitigate them.

Understanding Frame Rate Issues in Flutter Apps​

The frame rate of a Flutter app refers to the number of frames or screen updates displayed per second. The standard frame rate for smooth user experience is 60 frames per second (fps). If an app fails to achieve this frame rate consistently, it can result in stuttering animations, sluggish responsiveness, and an overall degraded user experience.

In Android, frame rate issues may manifest as App Not Responding (ANR) if the UI Thread gets blocked for 5000 milliseconds or more. If the UI Frames take 700 milliseconds or more to render it is a Frozen Frame situation and if it takes 16 milliseconds or more it is a Slow Frame situation.

In iOS, if the UI Thread is stuck for 250 milliseconds or more it is an App Hang, also called App Freeze, situation.

Common Causes of Frame Rate Issues​

1. Expensive Widget Rebuilds​

class MyExpensiveWidget extends StatelessWidget {
final ExpensiveData data;

const MyExpensiveWidget({required this.data});

@override
Widget build(BuildContext context) {
// Widget build logic that might be expensive
return ...;
}
}

To optimize widget rebuilds, use const constructors whenever possible. By using const, Flutter can efficiently skip the widget rebuild if the constructor parameters haven't changed.

2. Inefficient Animations​

​

class MyAnimationWidget extends StatefulWidget {
@override
_MyAnimationWidgetState createState() => _MyAnimationWidgetState();
}

class _MyAnimationWidgetState extends State<MyAnimationWidget>
with SingleTickerProviderStateMixin {
late AnimationController _controller;
late Animation<double> _animation;

@override
void initState() {
super.initState();
_controller = AnimationController(
duration: const Duration(milliseconds: 500),
vsync: this,
);
_animation = Tween(begin: 0.0, end: 1.0).animate(_controller);
_controller.forward();
}

@override
void dispose() {
_controller.dispose();
super.dispose();
}

@override
Widget build(BuildContext context) {
return AnimatedBuilder(
animation: _animation,
builder: (context, child) {
// Widget build logic using the animation value
return ...;
},
);
}
}

To optimize animations, use lightweight animations like Tween animations instead of heavy ones like Hero animations. Properly dispose of animation controllers to release resources and avoid unnecessary computations. Implement animation caching techniques, such as pre-loading and reusing animations, to reduce performance impact.

3. Inadequate Caching and Data Fetching​

​

class MyDataFetcher {
static final Map<String, dynamic> _cache = {};

static Future<dynamic> fetchData(String url) async {
if (_cache.containsKey(url)) {
return _cache[url];
} else {
final response = await http.get(Uri.parse(url));
final data = json.decode(response.body);
_cache[url] = data;
return data;
}
}
}

To optimize caching and data fetching, implement proper caching strategies. Utilize Flutter's built-in caching mechanisms, such as cached_network_image, to minimize repeated image downloads. Implement pagination techniques to fetch data incrementally instead of in one large chunk.

4. Simplify Layouts​

​

class MyComplexLayout extends StatelessWidget {
@override
Widget build(BuildContext context) {
return Container(
child: Column(
children: [
Expanded(
child: Row(
children: [
Flexible(child: Container()),
],
),
),
Expanded(
child: Container(),
),
],
),
);
}
}

To simplify layouts, minimize nested layouts and unnecessary constraints. Use appropriate layout widgets based on specific requirements. Avoid excessive use of Expanded and Flexible widgets when other layout techniques like SizedBox or AspectRatio can achieve the desired results.

Use App Performance Monitoring (APM) Tools​

Monitoring the frame rate of a Flutter app is crucial for maintaining optimal performance and delivering a smooth user experience. APM tools provide valuable insights into the app's rendering performance, allowing developers to identify and address frame rate issues effectively.

Two widely used tools for frame rate monitoring in Flutter are Firebase Performance Monitoring and Appxiom.

Conclusion​

Frame rate issues in Flutter apps can negatively impact the user experience, leading to reduced engagement and user satisfaction. By optimizing widget rebuilds, animations, caching and data fetching, as well as simplifying layouts, developers can ensure a smooth and responsive UI.

Remember to profile your app, optimize animations, simplify layouts, and follow best practices to address frame rate issues effectively. Use APM tools to continuously monitor app performance including frame rate issues. With careful attention to performance optimization, Flutter can deliver exceptional user experiences across various platforms.

Why Mobile App Testers and Developers Should Use APM Tools for Performance Monitoring.

Published: · Last updated: · 2 min read
Appxiom Team
Mobile App Performance Experts

Performance monitoring and continues bug monitoring are critical parts of the Mobile App development lifecycle. As mobile devices become more powerful and users expect more from their apps, it is essential to ensure that apps are performing well and are free of bugs. One way to achieve this is by using Application Performance Management (APM) tools.

APM tools are designed to help mobile app testers and developers detect and diagnose performance issues and bugs in their apps. These tools provide a wide range of information about an app's performance, including memory usage, CPU usage, network activity, and more. This information can be used to identify bottlenecks, memory leaks, and other issues that can negatively impact an app's performance.

One of the main benefits of using APM tools is that they can help app developers and testers find and fix performance issues before they become a problem for users. By identifying issues early in the development process, teams can make changes to improve performance and ensure that the app is stable and reliable. This can help reduce the number of crashes and improve the overall user experience.

Another benefit of using APM tools is that they can help developers and testers understand how users are interacting with their apps. This can be especially useful for understanding how different user segments are interacting with the app, which can help teams optimize the user experience and make improvements that will have the biggest impact.

In short, APM tools are an essential tool for mobile app testers and developers. They help teams identify and fix performance issues and bugs, improve the user experience, and ensure that apps are stable and reliable. By using APM tools, teams can deliver better quality apps and create a more positive user experience.

Visit appxiom.com to know more about how Appxiom can help you with monitoring performance and bugs in mobile apps.

Detecting ANR in Android Apps Using Firebase Crashlytics and Appxiom.

Published: · Last updated: · 2 min read
Appxiom Team
Mobile App Performance Experts

Firebase Crashlytics is used in most of the mobile apps to detect crashes. It also reports ANRs in Android with a detailed stacktrace.

Appxiom is a bug detection tool for Android and iOS apps. It captures a range of bugs including Crashes, ANRs, Memory Leaks, Memory Spikes, Abnormal Memory Usage, Frozen Frames, Slow Frames, HTTP API call issues, Screen Load Delays, and much more.

By definition ANR is triggered when the UI Thread gets blocked for 5 seconds or more. Appxiom detects and reports ANRs as and when the issue happens. It provides a chronologically ordered Activity Trail and a detailed Stacktrace that helps in locating where the ANR was triggered.

In Firebase ANRs get captured only when the user opts to Force Quit the app and then reopen it. This selection is done when the dialog message pops up asking if the app should Force Quit or it should wait to see if the UI Thread comes back. That means if the user waits and the UI Thread comes back to normalcy the ANR will not be reported. Also if the user decides to not come back the Firebase will not report the ANR.

ANR detection in Appxiom & FirebaseA detailed write up on how to use Appxiom to detect the root cause of ANR is available here https://www.blog.appxiom.com/post/detecting-and-fixing-anr-in-android-apps.

To know more about how Appxiom can help you in detecting bugs, visit https://appxiom.com. BTW, the tool works seamlessly in development, testing and live phases.